ARC-Challenge 데이터 셋 로드
from eval_datasets.types.arc import ARCDataset


arc_dataset = ARCDataset(
    path_or_url="allenai/ai2_arc",
    subset="ARC-Challenge",
    split="validation",
    use_llama_3_1_prompts=False,
)

print(
    "ARC-Challenge 데이터 개수:",
    len(arc_dataset),
)
공식 ARC Dataset은 문제와 선택지를 읽어 다음을 생성한다.
- zs_cotless_messages: Direct Answer 프롬프트
- zs_cot_messages: CoT 프롬프트
- answerKey: 정답 선택지 문자
- answer: 정답 선택지 내용
ARC 프롬프트 준비 함수
from copy import deepcopy


def prepare_arc_direct_messages(example):

    messages = deepcopy(
        example["zs_cotless_messages"]
    )

    if (
        len(messages) == 0
        or messages[-1]["role"] != "assistant"
    ):
        messages.append(
            {
                "role": "assistant",
                "content": "Answer: ",
            }
        )

    return messages


def prepare_arc_cot_messages(example):

    return deepcopy(
        example["zs_cot_messages"]
    )
GSM8K에서는 Direct prefix가 $\boxed{였지만, ARC는 객관식이므로 공식 코드가 사용하는 Answer: 를 넣는다.
Greedy 함수 정의
def generate_response(
    messages,
    max_new_tokens,
):
    """
    Qwen 모델로 greedy decoding을 수행한다.

    원 논문의 vLLM 설정:
    - temperature = 0
    - top_p = 1
    - rollout = 1

    Transformers 대응 설정:
    - do_sample = False
    - num_beams = 1
    """

    has_assistant_prefill = (
        len(messages) > 0
        and messages[-1]["role"] == "assistant"
    )

    if has_assistant_prefill:
        # 마지막 assistant 메시지 뒤를 이어서 생성
        prompt_text = tokenizer.apply_chat_template(
            messages,
            tokenize=False,
            continue_final_message=True,
        )

        assistant_prefix = messages[-1]["content"]

    else:
        # 새로운 assistant 답변 시작
        prompt_text = tokenizer.apply_chat_template(
            messages,
            tokenize=False,
            add_generation_prompt=True,
        )

        assistant_prefix = ""

    encoded = tokenizer(
        prompt_text,
        return_tensors="pt",
    )

    device = next(model.parameters()).device

    encoded = {
        key: value.to(device)
        for key, value in encoded.items()
    }

    input_length = encoded["input_ids"].shape[1]

    with torch.inference_mode():
        output_ids = model.generate(
            **encoded,

            max_new_tokens=max_new_tokens,

            # Greedy decoding
            do_sample=False,
            num_beams=1,

            eos_token_id=tokenizer.eos_token_id,
            pad_token_id=tokenizer.pad_token_id,

            use_cache=True,
        )

    # 입력 프롬프트를 제외하고 새로 생성한 부분만 가져옴
    generated_ids = output_ids[0, input_length:]

    continuation = tokenizer.decode(
        generated_ids,
        skip_special_tokens=True,
    ).strip()

    # Direct 조건은 '$\boxed{'가 입력에 포함돼 있었으므로
    # 평가를 위해 다시 앞에 붙여서 전체 응답을 복원
    return (
        assistant_prefix + continuation
    ).strip()
ARC 문제와 공식 프롬프트 확인
arc_example = arc_dataset[0]

print("question")
print(arc_example["question"])

print("\n choice")

for label, text in zip(
    arc_example["choices"]["label"],
    arc_example["choices"]["text"],
):
    print(f"{label}: {text}")

print("\n정답 문자:", arc_example["answerKey"])
print("정답 내용:", arc_example["answer"])


arc_direct_messages = (
    prepare_arc_direct_messages(
        arc_example
    )
)

arc_cot_messages = (
    prepare_arc_cot_messages(
        arc_example
    )
)


print("\n Direct message")

for message in arc_direct_messages:
    print(f"[{message['role']}]")
    print(message["content"])
    print()


print("CoT message")

for message in arc_cot_messages:
    print(f"[{message['role']}]")
    print(message["content"])
    print()
question
Juan and LaKeisha roll a few objects down a ramp. They want to see which object rolls the farthest. What should they do so they can repeat their investigation?
choice
A: Put the objects in groups.
B: Change the height of the ramp.
C: Choose different objects to roll.
D: Record the details of the investigation.
정답 문자: D
정답 내용: Record the details of the investigation.
Direct message
[system]
You are a helpful AI assistant that will answer reasoning questions. You will always say at the end "Answer: <Your Answer Letter Choice>". You must only pick one answer and you must end your response with "Answer: <Your Answer Letter Choice>" everytime!
[user]
Juan and LaKeisha roll a few objects down a ramp. They want to see which object rolls the farthest. What should they do so they can repeat their investigation?
( A ) Put the objects in groups.
( B ) Change the height of the ramp.
( C ) Choose different objects to roll.
( D ) Record the details of the investigation.
Only write the answer in the format: "Answer: <your answer>". You must always give an answer. You may only pick one answer choice, if you think multiple are correct only pick the one you think is best.
[assistant]
Answer:
CoT message
[system]
You are a helpful AI assistant that will answer reasoning questions. You may reason over the question but you will always say at the end "Answer: <Your Answer Letter Choice>". You must only pick one answer and you must end your response with "Answer: <Your Answer Letter Choice>" everytime!
[user]
Juan and LaKeisha roll a few objects down a ramp. They want to see which object rolls the farthest. What should they do so they can repeat their investigation?
( A ) Put the objects in groups.
( B ) Change the height of the ramp.
( C ) Choose different objects to roll.
( D ) Record the details of the investigation.
Think step by step before giving your final answer to the question. When you are ready to answer write the answer in the format: "Answer: <your answer>". You must always give an answer at the end. You may only pick one answer choice, if you think multiple are correct only pick the one you think is best.
ARC 전체 실험 함수 정의
from pathlib import Path
from time import perf_counter

import pandas as pd
from tqdm.auto import tqdm


def run_arc_experiment(
    dataset,
    num_samples,
    output_csv,
    direct_max_new_tokens=10,
    cot_max_new_tokens=1024,
):
    """
    동일한 ARC-Challenge 문제에 대해

    1. Zero-shot Direct Answer
    2. Zero-shot Chain-of-Thought

    를 실행하고 공식 ARC evaluator로 평가한다.
    """

    output_path = Path(output_csv)

    output_path.parent.mkdir(
        parents=True,
        exist_ok=True,
    )

    # 기존 결과가 있으면 이어서 실행
    if output_path.exists():
        previous_results = pd.read_csv(
            output_path
        )

        records = previous_results.to_dict(
            "records"
        )

        completed_indices = set(
            previous_results["index"]
            .astype(int)
            .tolist()
        )

        print(
            f"기존 ARC 결과 "
            f"{len(completed_indices)}개를 "
            f"불러왔습니다."
        )

    else:
        records = []
        completed_indices = set()

    target_count = min(
        num_samples,
        len(dataset),
    )

    for index in tqdm(
        range(target_count)
    ):

        if index in completed_indices:
            continue

        example = dataset[index]

        question = str(
            example.get(
                "question",
                "",
            )
        )

        gold_label = str(
            example.get(
                "answerKey",
                "",
            )
        )

        gold_answer = str(
            example.get(
                "answer",
                "",
            )
        )

        num_choices = len(
            example["choices"]["label"]
        )

        try:
            # -------------------------
            # 공식 프롬프트 준비
            # -------------------------
            direct_messages = (
                prepare_arc_direct_messages(
                    example
                )
            )

            cot_messages = (
                prepare_arc_cot_messages(
                    example
                )
            )

            # -------------------------
            # Direct 실행
            # -------------------------
            direct_start = perf_counter()

            direct_response = (
                generate_response(
                    direct_messages,
                    max_new_tokens=(
                        direct_max_new_tokens
                    ),
                )
            )

            direct_seconds = (
                perf_counter()
                - direct_start
            )

            direct_metric = (
                dataset.evaluate_response(
                    [direct_response],
                    example,
                )[0]
            )

            # -------------------------
            # CoT 실행
            # -------------------------
            cot_start = perf_counter()

            cot_response = (
                generate_response(
                    cot_messages,
                    max_new_tokens=(
                        cot_max_new_tokens
                    ),
                )
            )

            cot_seconds = (
                perf_counter()
                - cot_start
            )

            cot_metric = (
                dataset.evaluate_response(
                    [cot_response],
                    example,
                )[0]
            )

            # -------------------------
            # 출력 토큰 수
            # -------------------------
            direct_tokens = len(
                tokenizer.encode(
                    direct_response,
                    add_special_tokens=False,
                )
            )

            cot_tokens = len(
                tokenizer.encode(
                    cot_response,
                    add_special_tokens=False,
                )
            )

            direct_model_answer = (
                direct_metric.get(
                    "model_answer"
                )
            )

            cot_model_answer = (
                cot_metric.get(
                    "model_answer"
                )
            )

            direct_correct = bool(
                direct_metric.get(
                    "correct",
                    False,
                )
            )

            cot_correct = bool(
                cot_metric.get(
                    "correct",
                    False,
                )
            )

            direct_unparsable = (
                direct_model_answer is None
            )

            cot_unparsable = (
                cot_model_answer is None
            )

            # 원 논문 실행 스크립트는 객관식 답을
            # 추출하지 못하면 무작위 정답 확률을 점수로 사용
            direct_paper_score = (
                1 / num_choices
                if direct_unparsable
                else int(direct_correct)
            )

            cot_paper_score = (
                1 / num_choices
                if cot_unparsable
                else int(cot_correct)
            )

            record = {
                "dataset": "ARC-Challenge",
                "index": index,
                "question": question,

                "gold_label": gold_label,
                "gold_answer": gold_answer,

                "direct_model_answer": (
                    direct_model_answer
                ),
                "cot_model_answer": (
                    cot_model_answer
                ),

                "direct_correct": (
                    direct_correct
                ),
                "cot_correct": (
                    cot_correct
                ),

                "direct_paper_score": (
                    direct_paper_score
                ),
                "cot_paper_score": (
                    cot_paper_score
                ),

                "direct_unparsable": (
                    direct_unparsable
                ),
                "cot_unparsable": (
                    cot_unparsable
                ),

                "direct_output_tokens": (
                    direct_tokens
                ),
                "cot_output_tokens": (
                    cot_tokens
                ),

                "direct_seconds": (
                    direct_seconds
                ),
                "cot_seconds": (
                    cot_seconds
                ),

                "direct_response": (
                    direct_response
                ),
                "cot_response": (
                    cot_response
                ),

                "error": "",
            }

        except Exception as error:
            record = {
                "dataset": "ARC-Challenge",
                "index": index,
                "question": question,

                "gold_label": gold_label,
                "gold_answer": gold_answer,

                "direct_model_answer": None,
                "cot_model_answer": None,

                "direct_correct": False,
                "cot_correct": False,

                "direct_paper_score": 0,
                "cot_paper_score": 0,

                "direct_unparsable": True,
                "cot_unparsable": True,

                "direct_output_tokens": 0,
                "cot_output_tokens": 0,

                "direct_seconds": 0,
                "cot_seconds": 0,

                "direct_response": "",
                "cot_response": "",

                "error": repr(error),
            }

        records.append(record)

        # 문제 하나가 끝날 때마다 저장
        (
            pd.DataFrame(records)
            .sort_values("index")
            .to_csv(
                output_path,
                index=False,
                encoding="utf-8-sig",
            )
        )

    return (
        pd.DataFrame(records)
        .sort_values("index")
        .reset_index(drop=True)
    )
ARC 결과 요약 함수
from math import comb


def exact_mcnemar_pvalue(
    cot_only_correct,
    direct_only_correct,
):
    n = (
        cot_only_correct
        + direct_only_correct
    )

    if n == 0:
        return 1.0

    smaller = min(
        cot_only_correct,
        direct_only_correct,
    )

    one_tail = sum(
        comb(n, k) * (0.5 ** n)
        for k in range(
            smaller + 1
        )
    )

    return min(
        1.0,
        2 * one_tail,
    )


def boolean_series(series):
    """
    CSV를 다시 읽었을 때 문자열 True/False가
    들어오는 경우까지 안전하게 처리한다.
    """

    if series.dtype == bool:
        return series

    return (
        series.astype(str)
        .str.lower()
        .eq("true")
    )


def summarize_arc_results(results):
    valid = results[
        results["error"].fillna("") == ""
    ].copy()

    if len(valid) == 0:
        raise ValueError(
            "정상 완료된 ARC 결과가 없습니다."
        )

    direct_correct = boolean_series(
        valid["direct_correct"]
    )

    cot_correct = boolean_series(
        valid["cot_correct"]
    )

    both_correct = int(
        (
            direct_correct
            & cot_correct
        ).sum()
    )

    cot_only = int(
        (
            (~direct_correct)
            & cot_correct
        ).sum()
    )

    direct_only = int(
        (
            direct_correct
            & (~cot_correct)
        ).sum()
    )

    both_wrong = int(
        (
            (~direct_correct)
            & (~cot_correct)
        ).sum()
    )

    direct_accuracy = (
        direct_correct.mean()
    )

    cot_accuracy = (
        cot_correct.mean()
    )

    # 논문 스크립트 방식:
    # unparseable은 무작위 정답 확률 점수
    direct_paper_accuracy = (
        valid[
            "direct_paper_score"
        ].mean()
    )

    cot_paper_accuracy = (
        valid[
            "cot_paper_score"
        ].mean()
    )

    return pd.DataFrame(
        {
            "항목": [
                "정상 완료 문제 수",

                "Direct 공식 정확도",
                "CoT 공식 정확도",
                "공식 CoT-Direct 차이(%p)",

                "Direct 논문식 점수",
                "CoT 논문식 점수",
                "논문식 CoT-Direct 차이(%p)",

                "둘 다 정답",
                "CoT만 정답",
                "Direct만 정답",
                "둘 다 오답",

                "Direct 답 추출 실패율",
                "CoT 답 추출 실패율",

                "Direct 평균 출력 토큰",
                "CoT 평균 출력 토큰",

                "Direct 평균 생성 시간",
                "CoT 평균 생성 시간",

                "Exact McNemar p-value",
            ],
            "값": [
                len(valid),

                direct_accuracy,
                cot_accuracy,
                (
                    cot_accuracy
                    - direct_accuracy
                ) * 100,

                direct_paper_accuracy,
                cot_paper_accuracy,
                (
                    cot_paper_accuracy
                    - direct_paper_accuracy
                ) * 100,

                both_correct,
                cot_only,
                direct_only,
                both_wrong,

                boolean_series(
                    valid[
                        "direct_unparsable"
                    ]
                ).mean(),

                boolean_series(
                    valid[
                        "cot_unparsable"
                    ]
                ).mean(),

                valid[
                    "direct_output_tokens"
                ].mean(),

                valid[
                    "cot_output_tokens"
                ].mean(),

                valid[
                    "direct_seconds"
                ].mean(),

                valid[
                    "cot_seconds"
                ].mean(),

                exact_mcnemar_pvalue(
                    cot_only,
                    direct_only,
                ),
            ],
        }
    )
20문제 선행 실험
ARC_OUTPUT_FILE = (
    "results/"
    "qwen2_7b_arc_challenge_v1.csv"
)


arc_results = run_arc_experiment(
    dataset=arc_dataset,

    # 선행실험
    num_samples=20,

    output_csv=ARC_OUTPUT_FILE,

    # 공식 ARC 설정
    direct_max_new_tokens=10,
    cot_max_new_tokens=1024,
)


arc_results.head()
GSM8K Dataset 때와 마찬가지로 20문제를 먼저 선행 실험했다
| 항목 | 값 |
| 정상 완료 문제 수 | 20.000000 |
| Direct 공식 정확도 | 0.800000 |
| CoT 공식 정확도 | 0.750000 |
| 공식 CoT-Direct 차이(%p) | -5.000000 |
| Direct 논문식 점수 | 0.800000 |
| CoT 논문식 점수 | 0.750000 |
| 논문식 CoT-Direct 차이(%p) | -5.000000 |
| 둘 다 정답 | 15.000000 |
| CoT만 정답 | 0.000000 |
| Direct만 정답 | 1.000000 |
| 둘 다 오답 | 4.000000 |
| Direct 답 추출 실패율 | 0.000000 |
| CoT 답 추출 실패율 | 0.000000 |
| Direct 평균 출력 토큰 | 6.750000 |
| CoT 평균 출력 토큰 | 42.750000 |
| Direct 평균 생성 시간 | 0.125494 |
| CoT 평균 생성 시간 | 0.878873 |
| Exact McNemar p-value | 1.000000 |
이 결과를 보면 알 수 있듯이 20개의 Dataset에서는 오히려 CoT보다 Direct answering에서의 답변의 정확도가 더 좋았다. 논문에서 말한 CoT가 오히려 knowledge 분야에서는 크게 도움이 되지 않을 수 있다는 것을 보여준다
원문 재현
마지막으로 같은 CSV를 사용하여 전체 데이터셋으로 전체 validation까지 이어서 실행했다.
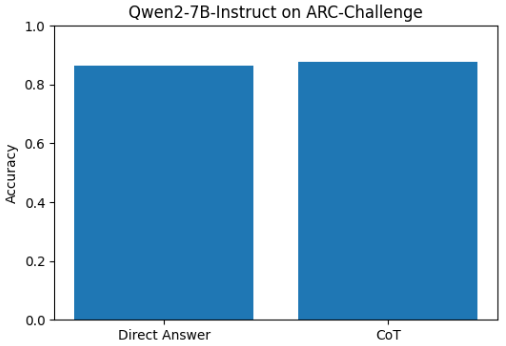
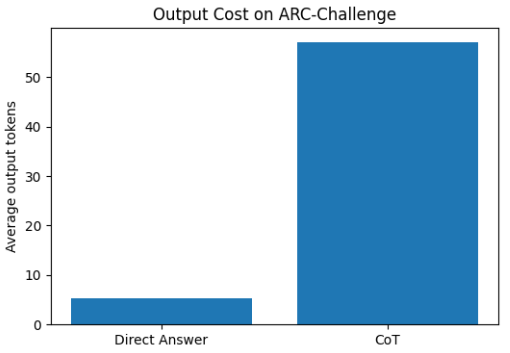
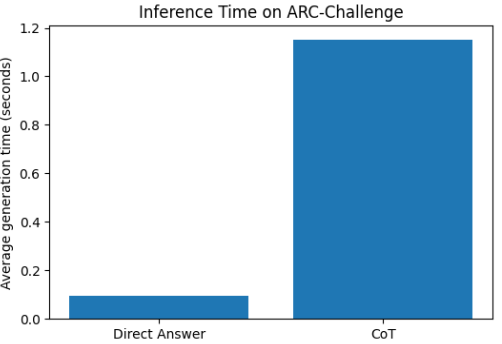
Direct answering과 CoT의 정확도에서는 거의 차이가 없지만 응답시간, 토큰 수에서 Direct answering이 압도적인 우세를 보여준다.
결과적으로 Qwen2-7B-Instruct를 대상으로 ARC-Challenge에서 Zero-shot Direct Answer와 Zero-shot CoT를 비교한 결과, Direct Answer의 정확도는 85.03%, CoT의 정확도는 86.05%로 나타났다.
CoT에 따른 정확도 향상은 약 1.02%p에 불과했다. 이는 동일 모델의 GSM8K 실험에서 관찰된 약 72%p의 향상과 크게 대조된다. 따라서 중간 계산이 필요한 수학 추론에서는 CoT가 성능을 크게 높이지만, 이미 학습된 지식을 회상하여 답할 수 있는 지식 중심 문제에서는 CoT의 추가 효과가 제한적인 것으로 나타났다. 또한 CoT는 정확도 향상이 작음에도 출력 토큰 수와 생성 시간을 증가시키므로, 지식 중심 과제에서는 비용 대비 효율이 낮다고 해석할 수 있다. 이러한 결과는 CoT의 효과가 과제 유형에 따라 달라지며 수학적,기호적 추론에 선택적으로 적용해야 한다는 원 논문의 핵심 주장을 방향적으로 뒷받침한다.